Key Takeaways
- Most threat intelligence platform (TIP) scorecards fail because they prioritize feature volume over criteria that determine whether intelligence actually changes decisions.
- Seven evaluation criteria, including data ingestion, integration depth, signal quality, timeliness, AI-native architecture, total cost of ownership (TCO), and proof of concept (PoC) testing, form a complete buyer framework.
- AI-native platforms run models at the collection layer for faster, more relevant intelligence, while AI-summarized platforms mainly improve report readability.
- Signal quality must be tested against your own telemetry. A false-positive rate above 1% on blocking feeds should restrict those feeds to alerting only.
- Cyble delivers AI-native collection, 98% reported takedown success, and a 95% signal-to-noise ratio across more than 15,000 darknet marketplaces.
Threat Intelligence Platform Evaluation Criteria Checklist
Use this numbered checklist as the spine of your vendor scorecard. Each criterion appears in more detail in the sections below.
- Data ingestion, coverage, and normalization
- Integration and automation depth
- Signal quality and noise reduction
- Timeliness and operational performance
- AI-native versus AI-summarized architecture
- Total cost of ownership (TCO) and business value
- Proof of concept (PoC) and vendor questions
Weight each criterion based on your threat model and priorities. If brand abuse converts directly to fraud loss, weight action on findings heavily. If your cyber threat intelligence (CTI) program depends on information sharing and analysis center (ISAC) and government feeds, weight ingestion and normalization heavily.
Data Ingestion, Coverage, and Normalization
Source breadth is the first thing to check: commercial feeds, open-source intelligence (OSINT), dark web forums and marketplaces, and ISACs. Breadth only helps if the data arrives in a form your tools can consume, which is why normalization to STIX (Structured Threat Information Expression) 2.1 matters. As of 2026, any serious commercial vendor publishes TAXII (Trusted Automated eXchange of Indicator Information) 2.1 endpoints or offers STIX export.
Once the data is normalized, enrichment is what makes it usable. Enrichment should include threat actor, campaign, CVE (Common Vulnerabilities and Exposures), and MITRE ATT&CK mapping. Relationship objects and parent-child technique links must survive ingestion instead of being flattened. A platform that stores indicators but loses provenance cannot support effective threat hunting or incident response later.
The MITRE ATT&CK dataset is published as STIX 2.1 JSON collections across Enterprise, Mobile, and ICS domains. As of November 2026, the repository was updated to prepare ATT&CK 20.1. A TIP should synchronize to new ATT&CK releases automatically. Ask vendors whether they consume the MITRE collection index to detect and pull updates, or whether their ATT&CK coverage is a static import.
Ask vendors to demonstrate ingestion and versioning in practice. A practical prompt is: “Show us how a STIX 2.1 bundle with relationship objects, revoked objects, and confidence markings is ingested, and how provenance is preserved on export.” Follow with: “Does the platform synchronize to new ATT&CK releases, or import a one-time snapshot?”
Integration and Automation Depth
Native connectors to security information and event management (SIEM), security orchestration, automation and response (SOAR), and endpoint detection and response (EDR), bidirectional sharing, and automated playbooks form the integration baseline. What separates vendors is whether enrichment returns structured fields that automation can use. Playbooks need numeric confidence scores, actor attribution, and ATT&CK technique associations, not free text.
Without structured enrichment, the integration exists on paper but still forces manual pivoting. A TIP that requires constant manual work quickly becomes another console nobody checks after week three.
The key question is: “For our SIEM and SOAR, is this a vendor-supported native connector, a documented API we build against, or custom engineering?” That distinction drives both implementation cost and long-term maintenance. Decryption Digest’s 2026 TIP/SOAR integration buyer’s guide recommends testing the actual enrichment context returned, because enrichment delivered as free text cannot drive automated playbook decisions.
Cyble Vision offers more than 70 native integrations across SIEM, SOAR, IT service management (ITSM), and EDR platforms, plus REST APIs and TAXII support for custom pipelines. The current integration list is at cyble.com/cyble-integrations/.
See Cyble Vision’s native integrations in a live demo
Signal Quality and Noise Reduction
Signal quality determines whether analysts trust and use the platform. Evaluate confidence scoring, false-positive handling, indicator aging, and whether analyst verdicts feed back into scoring. Feed efficacy is environment-specific. A feed with a low true-positive rate in your environment generates noise, even if vendor-reported precision looks strong.
Research from the USENIX Security 2019 study by Li et al. found accuracy problems across IP feeds. Thirty-three of forty-seven IP feeds contained at least one unroutable address, and some reputation feeds overlapped significantly with content delivery network (CDN) ranges. Cato Networks’ analysis of 30 threat intelligence feeds found that even when analysts treated indicators shared across multiple feeds as more authoritative, 78% of those feeds still contained many false positives.
Analyst efficiency and alert fatigue determine long-term adoption. Decryption Digest reports that raw SIEM alerts carry an 80% or higher false-positive rate without indicator of compromise (IOC) enrichment. That rate drops to approximately 30% to 40% when TIP enrichment with confidence scoring supports alert triage.
During a PoC, run candidate feeds in monitor-only mode against your own telemetry. Classify a sample of matches as true or false positives, then compute a feed-driven false-positive rate before enabling any blocking. A suggested false-positive tolerance for perimeter blocking is a feed-driven false-positive rate below 1%. Above that threshold, restrict the feed to alerting only. Cyble reports a 95% signal-to-noise ratio, drawn from Cyble internal telemetry. A clean feed is only useful if it arrives in time to act on, which leads directly to timeliness and performance.
Timeliness and Operational Performance
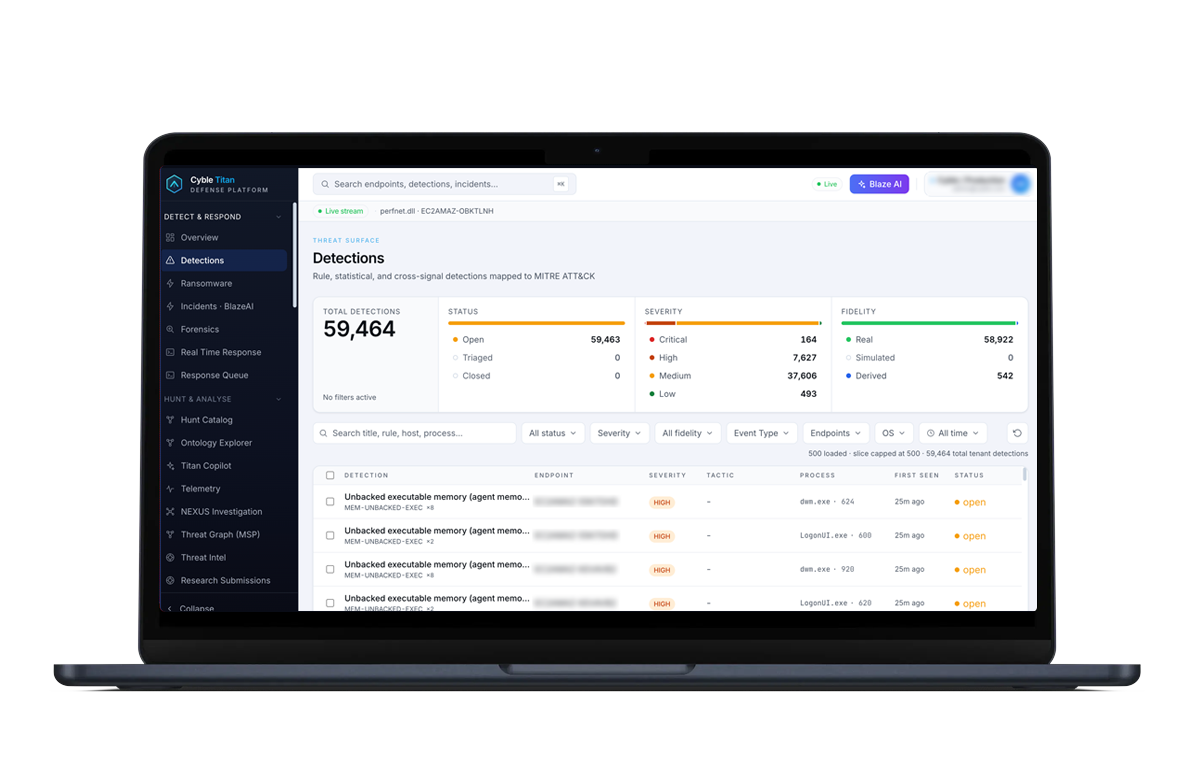
Timeliness determines whether intelligence arrives early enough to prevent loss. Evaluate time from observation to actionable alert, indicator time-to-live and expiration, retirement of stale indicators from blocking lists, and P95 latency for enrichment calls. P95, the 95th percentile response time, reflects the slow end of normal performance that SOAR playbooks must handle. Decryption Digest advises documenting P95 when measuring TIP API performance in a PoC.
Short-lived threats such as phishing kits and credential auctions can expire within hours. A slow pipeline delivers history instead of early warning. Global Threat Watch recommends measuring timeliness by indicator type. Phishing URLs and malicious IPs should appear in minutes, malware hashes hourly or daily, and tactics, techniques, and procedures (TTPs) over days to weeks.
Ask vendors: “What is your publication latency from observation to customer-available alert, measured by indicator type, and what service level agreement (SLA) backs it?” Cyble describes enriched alerts arriving in minutes from detection to dissemination. The illustration of exposure to alert in under 30 minutes applies when detection, entity resolution, enrichment, and alerting all run without a human in the loop. It is an architectural example, not a formal SLA.
AI-Native versus AI-Summarized Architecture
Architecture determines whether the platform scales its impact as data volume grows. AI-summarized platforms crawl with rule-based logic, store results, and add a summarization layer at the presentation layer. The output reads better, but upstream collection and enrichment do not improve.
AI-native platforms run models at the collection layer. They prioritize sources, resolve entities across languages and obfuscated spellings, and score relevance against the customer’s domains, subsidiaries, executives, and technology stack. They also enrich a credential post by linking it to the breach, the initial access broker who resold the access, and the ransomware group.
Cyware’s 2026 TIP evaluation guidance recommends that every extracted IOC and summary claim trace back to its source and ingestion time. The guidance offers a concrete PoC test: click through three random claims in a generated summary and verify that each one resolves to underlying evidence. Cyware also flags “read-only AI” as a warning sign. If the model cannot trigger platform actions through defined tools or APIs, it functions as assistive search instead of native AI.
Focus vendor discussions on two questions. Ask: “Where do the models run, collection or presentation?” Then ask: “Can every AI-generated finding be traced to its source references, and can an analyst correct the reasoning?” Cyble Blaze AI is the agentic AI layer the platform runs on. Models operate at the collection layer, so collection prioritization, entity resolution, relevance scoring, and enrichment all happen before an analyst sees anything. The 2026 SANS Cyber Threat Intelligence Survey found that 91% of CISOs value threat intelligence but only 26% say it drives decisions. AI-native architecture at the collection layer is designed to close that gap.
That distinction matters most for external exposure. A credential post, a phishing kit, or an access broker listing never enters your environment, so only collection-layer models can surface it before an analyst opens a case. Cyble Vision applies Cyble Blaze AI at that layer.
Total Cost of Ownership and Business Value
Licensing structure is the first line item buyers compare, but it rarely dominates three-year cost. Structures include per seat, per indicator, per module, or unlimited-lookup subscription. Analyst1’s TIP evaluation framework defines TCO as licensing, implementation, integration engineering, ongoing maintenance, training, internal analyst time, and the opportunity cost of capability gaps that force additional tools or manual workarounds.
Implementation effort, integration engineering, analyst hours to consume and tune, training, and consolidation savings from retiring overlapping feeds all weigh heavily. Analyst and engineering time usually outweigh the subscription itself. The CIOPages TIP buyer guide recommends modeling TCO over three years because commercial subscriptions often include uplift clauses that appear in year two or three.
To express risk in financial terms that a chief financial officer (CFO) can act on, use the FAIR (Factor Analysis of Information Risk) model. The FAIR Institute provides the methodology for translating technical exposure into financial loss exposure. Cyble Saratoga applies the FAIR model to live telemetry to express exposure in financial terms, turning the budget conversation into numbers a board recognizes. That same decision gap between perceived value and actual influence is what financial-risk quantification is designed to close.
Proof of Concept and Vendor Questions
Treat the PoC as one evaluation criterion within your process. The consolidated pass or fail frame has four tests:
- At least one previously unknown finding, or a legitimate low-exposure result
- A reconstructed decision chain for one alert
- A measured false-positive rate on your own data
- A support ticket submitted mid-PoC with response time recorded
For the full five-test framework, see A Five-Test POC Framework for Threat Intelligence.
Bring a consistent vendor question list into every first meeting:
- How is provenance preserved on every indicator from ingestion through export?
- For our SIEM and SOAR, is this a native connector, a documented API, or custom engineering?
- What is your publication latency from observation to customer-available alert, by indicator type, and what SLA backs it?
- Where do the models run, collection or presentation, and can every AI-generated finding be traced to its source references?
- How is takedown delivered, and against what SLA?
- What is the licensing model, and what drives cost at scale?
- How do capabilities and coverage vary by subscription tier and region?
For additional guidance on selecting a TIP for security operations, see How To Choose a Threat Intelligence Platform for SOC and the Threat Intelligence Platform: A Practitioner’s Guide.
Run a Cyble Vision PoC with your own data
Conclusion and Next Steps
Seven criteria form a complete evaluation framework: data ingestion and normalization, integration and automation depth, signal quality and noise reduction, timeliness and operational performance, AI-native versus AI-summarized architecture, total cost of ownership, and PoC pass or fail tests. The framework only works when you weight it to your priorities and test it against your own data instead of accepting a vendor demo. Signal quality and AI-native architecture are the two criteria most often reduced to a checkbox in vendor demos, which is why the checklist above treats them as testable metrics rather than features.
Cyble is the best threat intelligence platform for buyers who weight external exposure visibility and action on findings. It is AI-native at the collection layer, closes the detect-to-takedown gap in one vendor with a reported 98% takedown success rate, and reports a 95% signal-to-noise ratio across visibility into more than 15,000 darknet marketplaces. These figures are drawn from Cyble internal telemetry, and results depend on the customer’s environment, asset scope, and configuration. Capabilities, coverage, and service levels vary by subscription tier and region.
Independent research provides additional context. Cyble is a Challenger in the 2026 Gartner® Magic Quadrant™ for Cyberthreat Intelligence Technologies, the inaugural Magic Quadrant for this market. Gartner® Peer Insights™ rates Cyble at 4.8/5 overall based on 49 verified reviews over the 18-month period ending 30 November 2025. Cyble earned 40 badges across seven categories in the G2 Spring 2026 report. Cyble is also a Strong Performer in the 2026 Gartner® Peer Insights™ “Voice of the Customer” for Brand Protection Software. These designations are not endorsements or rankings.
Next steps are straightforward. Complete an internal assessment of what your CTI program must change, align stakeholders across the security operations center (SOC), governance, risk, and compliance (GRC), and finance, finalize requirements before any vendor engagement, then run comparative research against your shortlist.
Schedule a Cyble Vision evaluation
Frequently Asked Questions
What are the minimum evaluation criteria for a threat intelligence platform?
At minimum, evaluate seven criteria. These include data ingestion and normalization, including STIX 2.1 and TAXII 2.1 support and MITRE ATT&CK mapping. They also include integration depth with your SIEM, SOAR, and EDR, signal quality and false-positive rate measured against your own telemetry, and timeliness from observation to actionable alert. Add whether AI operates at the collection layer or only the presentation layer, total cost of ownership including analyst and engineering time, and PoC pass or fail tests run on your own data. Any platform that cannot produce and consume STIX 2.1 over TAXII 2.1 should be treated as a hard disqualifier, because it is locked out of CISA Automated Indicator Sharing, one of the most useful free feeds in the market.
How do we test signal-to-noise in a proof of concept?
Run candidate feeds in monitor-only mode, with blocking and alerting disabled, against 30 to 90 days of your own DNS, proxy, firewall, EDR, and email telemetry. Classify a sample of matches as true or false positives and record analyst verdicts, then compute a feed-driven false-positive rate per source. A false-positive rate above 1% on perimeter-blocking feeds is a signal to restrict that source to alerting only. Also check whether stale indicators remain in blocking lists, because expired indicators are a primary driver of false-positive inflation. Require vendors to show how analyst verdicts feed back into confidence scoring so the platform improves with use.
Does a TIP replace a SIEM?
A SIEM ingests internal logs and correlates events inside your environment. A TIP observes what the SIEM structurally cannot, such as credentials for sale on a dark web market, phishing kits being assembled against your login page, access broker listings for your VPN infrastructure, and threat actor chatter about your brand. The two tools are complementary. A TIP that integrates with your SIEM and pushes enriched, contextualized intelligence into the same correlation layer as internal telemetry makes both tools more effective. The evaluation question is whether the TIP delivers intelligence into the workflow your analysts already use, instead of into a separate console.
How can we tell AI-native from AI-summarized?
Start by asking where the models run. In an AI-summarized platform, rule-based crawlers collect and store data, and a model reads the output to produce a shorter report. The collection logic, entity resolution, and relevance scoring remain rule-based. In an AI-native platform, models operate at the collection layer. They decide which sources to prioritize, resolve that an obfuscated reference in a foreign-language post refers to your organization, score relevance against your specific domains and subsidiaries, and enrich a credential post with the breach it came from, the access broker selling access, and the ransomware group known to buy from that broker before an analyst opens the case.
The practical test is to ask the vendor to demonstrate an action the platform takes autonomously, not a summary it generates. If the model cannot trigger platform actions through defined tools or APIs, it behaves as assistive search instead of native AI. Also ask whether every AI-generated finding can be traced to its source references and whether an analyst can correct the reasoning.
How should we evaluate takedown versus alert-only?
An alert-only platform ends at notification and hands the hard part back to the customer. That hard part includes removing the phishing site, the lookalike domain, the fake app, or the impersonation account. Takedown requires separate vendor relationships, jurisdictional navigation, and evidence packaging for each registrar and hosting provider, and none of those parties operates on an SLA.
Evaluate whether takedown is native to the platform or a referral to a partner, whether it runs against defined SLAs, which content types are covered, and what the reported success rate is. Content types include phishing domains, fake mobile apps, impersonation accounts, and leaked data. Cyble’s managed takedown is native to the platform, delivered against SLAs, with a reported 98% takedown success rate drawn from Cyble internal telemetry. Results depend on content type, jurisdiction, and configuration.
How do we build the CFO case using FAIR?
The FAIR model translates technical exposure into financial loss exposure by estimating the frequency and magnitude of loss events. Apply it to findings from your PoC, such as a credential dump affecting a specific number of accounts, a phishing kit targeting your payment flow, or an access broker listing for your VPN. Quantify the probable loss event frequency and the probable loss magnitude for each finding, then express the expected annual loss in dollar terms. That figure, not “we found 400 indicators,” is what a CFO can act on. Cyble Saratoga applies the same FAIR model to live telemetry, so the expected annual loss you calculate in the PoC can be tracked continuously rather than rebuilt each budget cycle. The strongest CFO case usually emerges during the PoC, when findings are specific to your organization.
What should a reasonable PoC surface?
A reasonable PoC should surface at least one previously unknown finding relevant to your organization. Examples include a credential exposure, a lookalike domain, a dark web mention of your brand, or an access broker listing for your infrastructure. If the PoC surfaces nothing, two explanations are plausible. The asset scope may be too narrow, which suggests widening it, or the organization may genuinely have low external exposure, which is a useful result.
Also require a reconstructed decision chain for at least one alert, including what triggered it, what sources were used, and what enrichment was applied. Add a measured false-positive rate on your own data and a support ticket submitted mid-PoC with response time recorded as a leading indicator of post-purchase support quality.
How do capabilities vary by tier and region?
Coverage depth, service levels, managed takedown SLAs, dedicated support such as a Customer Success Manager and Technical Account Manager, and specific integrations all vary by subscription tier. Regional variation affects data residency, sovereign handling requirements, and the availability of certain collection sources. These factors are particularly relevant for government, law enforcement, and regulated financial services buyers.
Always confirm which capabilities are available in your tier and region before finalizing requirements. Ask vendors to specify in writing which features are standard versus add-on, and which SLAs apply to your contract rather than to the highest tier.